
NOTE
2.12 BloomFilter
Why BloomFilter is needed, how it works, use cases, and a Go implementation.
This is a historical learning note and may contain outdated or incomplete understanding.
1. Why BloomFilter Is Needed
1.1. BloomFilter vs HashSet
A website has 2 billion URLs in a blacklist. How should this blacklist be stored? If a URL is entered, how can we quickly determine whether it is in this blacklist, while keeping within a given memory limit such as 500 MB?
- If HashSet is used
- It can provide O(1) time efficiency, but the space requirement is too high.
- If each URL string is hashed into an Integer occupying 4 Bytes,
2 billion*4/1024/1024/1024=7.45Gof memory is required.
1.2. BloomFilter vs BitMap
- BitMap does not support elements other than integers
- If BitMap stores integers with a very large range, it still uses a lot of space. BloomFilter can use less space because one bit can represent multiple meanings through multiple hash functions
- For example, for values from 1 to 1 billion, the bitmap has 1 billion bits, which is about 120 MB
2. What Is BloomFilter
- It consists of a long sequence of binary bits and a group of hash functions.
- It is used to quickly determine whether an element is in a set
- Advantages: balances time and space efficiency
- Time complexity: O(k), where k is the number of hash functions
- Space complexity: O(m), where m is the number of bits
- Disadvantage: there is a certain false-positive rate (an element that is not in the set may be considered to be in the set)
- Advantages: balances time and space efficiency
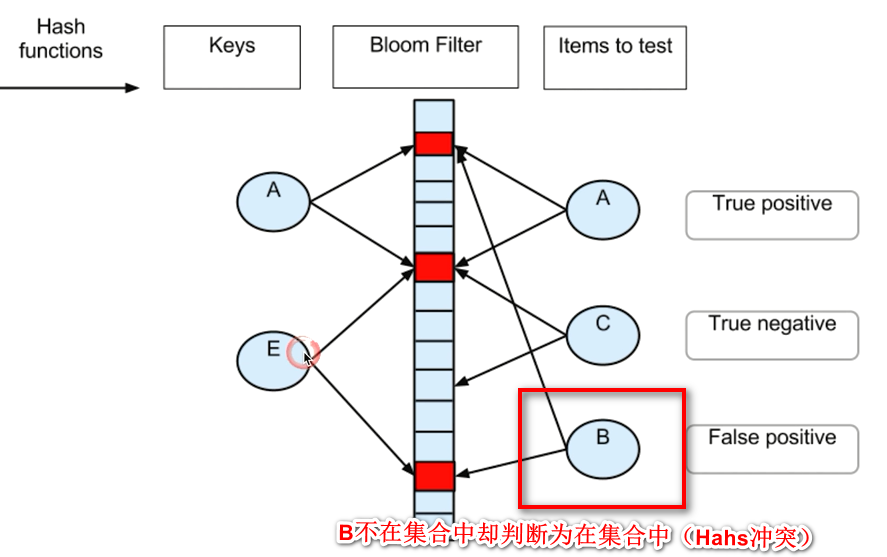
2.1. How to Reduce the False-Positive Rate
Multiple hash functions can be used to calculate positions and set multiple bits to 1. When checking, calculate with the same hash functions. If all these bits are 1, the element may exist; if any one is not 1, it does not exist.
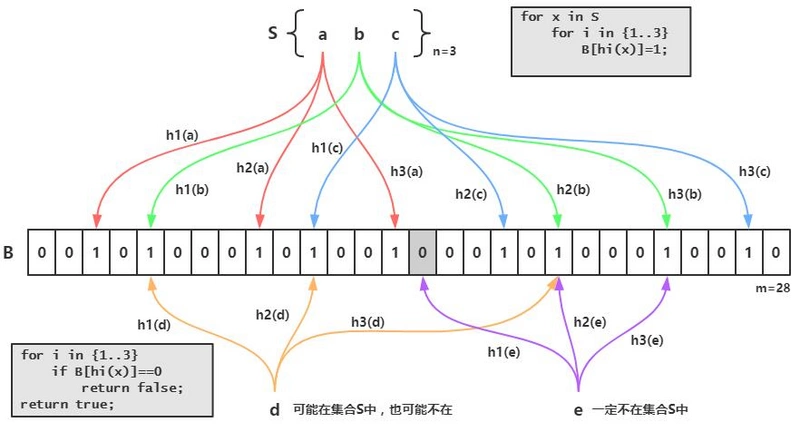 The key is deciding how long the bit array should be and how many hash functions should be used.
These can be calculated from the acceptable false-positive rate fpp and the total number of elements n.
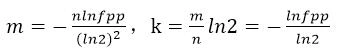
3. BloomFilter Use Cases
- Blacklists
- URL deduplication
- Spell checking
- Key validation in Key-Value cache systems
- ID validation, for example, when an order system queries whether an order ID exists, it can return directly if it does not exist
- Google uses BloomFilter in BigTable to avoid looking for nonexistent entries on disk
- Web crawlers also use BloomFilter to deduplicate URLs
4. Implementation
4.1. Google Guava
4.2. Redis
4.3. Golang
4.3.1. Data Structure
- bits
- hash functions
4.3.2. API
type IBloomFilter interface {
	// Print the Bloom filter
	String() string
	// Whether the Bloom filter contains key
	Contains(key interface{}) bool
	// Update the value corresponding to key in the Bloom filter
	Put(key interface{})
}
4.3.3. Implementation
import (
	"fmt"
	"hash/crc32"
	"math"
)

type BloomFilter struct {
	// Total number of bits
	bitSize int
	// Bits implemented using int64
	bits []int64
	// Number of hash functions
	hashFuncSize int
}

// n: data size
// p: false-positive rate, range (0, 1)
func NewBloomFilter(n int, p float64) *BloomFilter {
	if n <= 0 || p <= 0 || p >= 1 {
		panic("wrong n or p")
	}
	// Calculate bitSize and hashFuncSize from the formulas
	bitSize := -int((float64(n) * math.Log(p)) / (math.Ln2 * math.Ln2))
	hashFuncSize := int(float64(bitSize) * math.Ln2 / float64(n))

	// Paging formula
	bitArraySize := (bitSize + 64 - 1) / 64
	bits := make([]int64, bitArraySize, bitArraySize)
	return &BloomFilter{
		bitSize:      bitSize,
		bits:         bits,
		hashFuncSize: hashFuncSize,
	}
}

func (b *BloomFilter) String() string {
	return fmt.Sprintf("bitsSize: %v, hashFuncSize: %v", b.bitSize, b.hashFuncSize)
}

func (b *BloomFilter) Contains(key interface{}) bool {
	// google guava bloom filter
	hash1 := hashCode(key)
	hash2 := hash1 >> 16
	for i := 1; i <= b.hashFuncSize; i++ {
		combinedHash := hash1 + (i * hash2)
		if combinedHash < 0 {
			combinedHash = ^combinedHash
		}
		// Generate a bit index
		index := combinedHash % b.bitSize
		// Check whether the bit at index is 0
		if !b.get(index) {
			return false
		}
	}

	return true
}

// Get the bit value at index
// true means 1, false means 0
func (b *BloomFilter) get(index int) bool {
	// First find which element of the int64 array contains the bit
	value := b.bits[index/64]
	// Then find which bit in that element
	var bit int64 = 1 << (index % 64)
	// To get a bit value, set that bit to 1 and all other bits to 0, then use AND
	return (value & bit) != 0
}

func (b *BloomFilter) Put(key interface{}) {
	// google guava bloom filter
	hash1 := hashCode(key)
	hash2 := hash1 >> 16
	for i := 1; i <= b.hashFuncSize; i++ {
		combinedHash := hash1 + (i * hash2)
		if combinedHash < 0 {
			combinedHash = ^combinedHash
		}
		// Generate a bit index
		index := combinedHash % b.bitSize
		// Set the bit at index
		b.set(index)
	}

}

// Set the bit at index to 1
func (b *BloomFilter) set(index int) {
	// First find which element of the int64 array contains the bit
	value := b.bits[index/64]
	// Then find which bit in that element
	var bit int64 = 1 << (index % 64)
	// To update a bit, set that bit to 1 and all other bits to 0, then use OR
	b.bits[index/64] = value | bit
}

// Calculate the hashCode of key
func hashCode(key interface{}) int {
	str := fmt.Sprintf("%v", key)
	v := int(crc32.ChecksumIEEE([]byte(str)))
	if v >= 0 {
		return v
	}
	return -v
}
4.3.3.1. Test
func TestBloomFilter(t *testing.T) {
	bloomFilter := NewBloomFilter(10_0000_0000, 0.01)
	for i := 1; i <= 1_00_0000; i++ {
		bloomFilter.Put(i)
	}

	count := 0
	for i := 1; i <= 1_00_0000; i++ {
		if bloomFilter.Contains(i) {
			count++
		}
	}
	fmt.Println(count==1_00_0000)

	count = 0
	for i := 1_00_0001; i <= 2_00_0000; i++ {
		if bloomFilter.Contains(i) {
			count++
		}
	}

	fmt.Println(count)
}
Discussion
Sign in with GitHub to comment. Discussions are stored as GitHub Issues.View on GitHub