
NOTE
2.9 Skip List
Skip-list basics, motivation, implementation, and expected complexity.
This is a historical learning note and may contain outdated or incomplete understanding.
1. What Is a Skip List
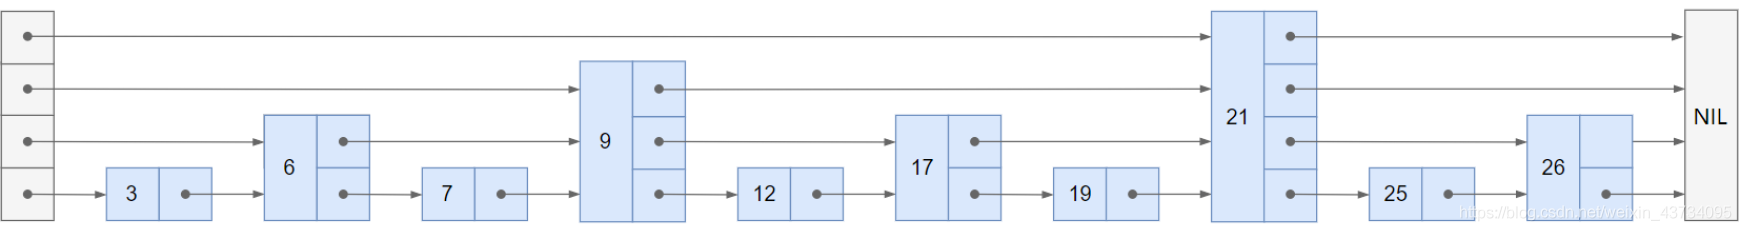
- Compared with a normal linked list, a skip list has two differences
- Nodes are connected through multi-level index pointers
- It has the concept of levels
1.1. Examples
- Normal linked list
- Skip list with 2 effective levels
- Skip list with 4 effective levels


1.2. Characteristics
- Randomized data structure
- The bottom level contains all elements in the skip list
- A typical space-for-time tradeoff. Insert/delete/search/update efficiency is O(logN)
2. Why Skip List Is Needed
- It brings the binary-search idea of sorted arrays to linked lists
- A sorted array can use binary search with O(logN) efficiency, while a sorted linked list can only achieve O(N), which is inefficient
- Red-black trees are complex to implement, so another data structure can be used as an alternative: the skip list
3. Implementation
3.1. Data Structure
- Dummy head node
- key
- value
- node pointer array
- Effective level count
3.2. API
type ISkipList interface {
	// Print the skip list
	String() string
	// Number of elements in the skip list
	Length() int
	// Whether the skip list is empty
	IsEmpty() bool
	// Add an element to the skip list: O(logN)
	Put(key model.Comparable, value interface{})
	// Whether the skip list contains key: O(logN)
	Contains(key model.Comparable) bool
	// Get the value corresponding to key: O(logN)
	Get(key model.Comparable) (interface{}, bool)
	// Delete the element corresponding to key: O(logN)
	Remove(key model.Comparable)
}
3.3. Implementation
const (
	// Probability value
	P = 0.25
	// Maximum number of levels
	MaxLevel = 32
)

type node struct {
	key   model.Comparable
	value interface{}
	next  []*node
}

func (n *node) String() string {
	return fmt.Sprintf("[%v:%v]", n.key, n.value)
}

func NewNode(key model.Comparable, value interface{}, level int) *node {
	return &node{
		key:   key,
		value: value,
		next:  make([]*node, level, level)}
}

type SkipList struct {
	// Dummy head node
	dummyHead *node
	// Number of active levels
	level int
	// Number of nodes
	length int
}

func NewSkipList() *SkipList {
	return &SkipList{
		dummyHead: NewNode(nil, nil, MaxLevel),
		level:     0,
		length:    0,
	}
}

func (s *SkipList) String() string {
	str := fmt.Sprintf("length=%v, level=%v, data={", s.length, s.level)
	for i := s.level - 1; i >= 0; i-- {
		current := s.dummyHead
		for current.next[i] != nil {
			str = fmt.Sprintf("%s%v ", str, current.next[i])
			current = current.next[i]
		}
		str = strings.TrimRight(str, " ")
		str += "\n"
	}
	str = strings.TrimRight(str, "\n")

	str += "}"
	return str
}

func (s *SkipList) Length() int {
	return s.length
}

func (s *SkipList) IsEmpty() bool {
	return s.length == 0
}

func (s *SkipList) Put(key model.Comparable, value interface{}) {
	current := s.dummyHead
	// To insert a node into the linked list, first locate its predecessor
	prev := make([]*node, s.level, s.level)
	for i := s.level - 1; i >= 0; i-- {
		cmp := -1
		for current.next[i] != nil {
			cmp = key.CompareTo(current.next[i].key)
			if cmp <= 0 {
				break
			}
			current = current.next[i]
		}

		// If found, just update the value
		if cmp == 0 {
			current.next[i].value = value
			return
		}

		// Here cmp < 0 means this is the predecessor; save it for insertion
		prev[i] = current
	}

	// Insert a new node
	newLevel := randomLevel()
	newNode := NewNode(key, value, newLevel)
	for i := 0; i < newLevel; i++ {
		// If level is greater than the current level count, create a new level
		if i >= s.level {
			s.dummyHead.next[i] = newNode
		} else {
			// Insert a node in the middle of the linked list
			newNode.next[i] = prev[i].next[i]
			prev[i].next[i] = newNode
		}
	}

	s.level = util.Max(s.level, newLevel)
	s.length++
}

func (s *SkipList) Contains(key model.Comparable) bool {
	_, ok := s.Get(key)
	return ok
}

func (s *SkipList) Get(key model.Comparable) (interface{}, bool) {
	current := s.dummyHead
	// 1. Start from the highest level and move downward one level at a time
	for i := s.level - 1; i >= 0; i-- {
		cmp := -1
		// 2. Each level is a linked list; compare nodes one by one
		for current.next[i] != nil {
			cmp = key.CompareTo(current.next[i].key)
			// 3. If the current node's key is smaller than the target key, continue to the right
			if cmp <= 0 {
				break
			}
			current = current.next[i]
		}
		// 4.1 Return when the key is found
		if cmp == 0 {
			return current.next[i].value, true
		}
		// 4.2 Otherwise continue on the next lower level
	}

	return nil, false
}

func (s *SkipList) Remove(key model.Comparable) {
	current := s.dummyHead
	// To delete a node from the linked list, its predecessor is needed
	prev := make([]*node, s.level, s.level)
	exists := false
	for i := s.level - 1; i >= 0; i-- {
		cmp := -1
		for current.next[i] != nil {
			cmp = key.CompareTo(current.next[i].key)
			if cmp <= 0 {
				break
			}
			current = current.next[i]
		}

		if cmp == 0 {
			exists = true
		}
		prev[i] = current
	}

	// If it does not exist, there is nothing to delete
	if !exists {
		return
	}

	// Delete the node from the linked list
	removedNode := current.next[0]
	for i := 0; i < len(removedNode.next); i++ {
		prev[i].next[i] = removedNode.next[i]
	}

	// After deleting a node, the number of levels may decrease
	// A level can be removed when its next pointer is nil
	newLevel := s.level - 1
	for newLevel > 0 && s.dummyHead.next[newLevel] == nil {
		s.level = newLevel
		newLevel--
	}

	s.length--
}

func randomLevel() int {
	level := 1
	// Randomly increase level, but never beyond MaxLevel
	for rand.Float64() < P && level < MaxLevel {
		level++
	}
	return level
}
3.3.1. Test
func TestSkipList(t *testing.T) {
	skipList := NewSkipList()
	e0 := model.NewElement(0)
	skipList.Put(e0, "e0")
	for i := 1; i < 100; i++ {
		e := model.NewElement(i)
		skipList.Put(e, fmt.Sprintf("e%v", i))

	}

	fmt.Println("After adding elements: ", skipList)

	fmt.Println("Contains e0? ", skipList.Contains(e0))
	get, _ := skipList.Get(e0)
	fmt.Println("Data corresponding to e0: ", get)

	skipList.Remove(e0)
	fmt.Println("After deleting e0: ", skipList)

	skipList.Remove(model.NewElement(6))
	fmt.Println("After deleting e6: ", skipList)

	skipList.Remove(model.NewElement(87))
	fmt.Println("After deleting e87: ", skipList)
}
Discussion
Sign in with GitHub to comment. Discussions are stored as GitHub Issues.View on GitHub