
Concurrency Programming (0): The Problem Space and Scope
Defines the scope as concurrency within a single process on a single machine, then connects shared variables, shared memory, message passing, language concurrency semantics, and hardware implementation.
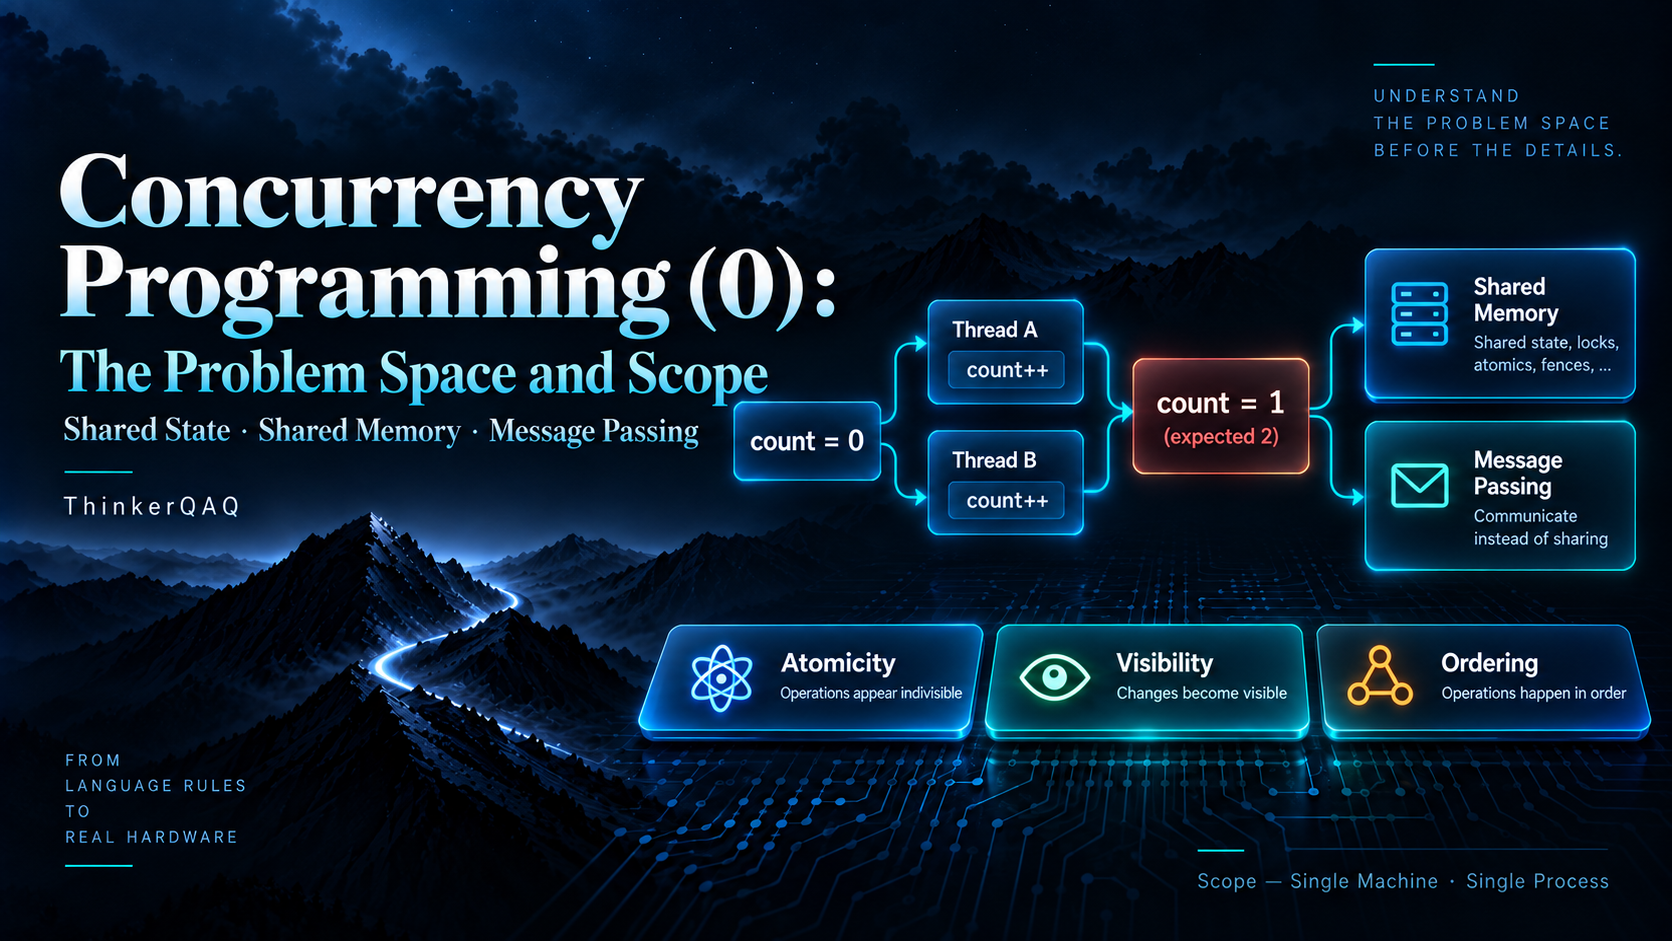
Table of Contents
- 1. Define the Scope First
- 2. Start with a Shared Variable
- 3. Two Main Coordination Models
- 4. Why Does This Code Work Correctly?
- 5. Languages Need to Define Concurrency Semantics
- 6. Why Do We Still Need to Go Down to the Hardware?
- 7. A Single Diagram for the Layers Covered in This Series
- 8. Next: Start with the Hardware
1. Define the Scope First
This series focuses only on:
Concurrency within a single process on a single machine.
In other words, we are concerned with multiple execution units inside the same process.
For example:
- Java Thread;
- Go Goroutine;
- Python Thread / asyncio Task.
Inter-process communication, distributed systems, and network communication are outside the scope of this series.
2. Start with a Shared Variable
Suppose a process contains this variable:
count = 0Now there are two execution units:
Thread A                    Thread B

count++                     count++
If A and B each execute once, is the final result guaranteed to be:
count = 2No.
Logically, count++ can be broken down into three steps:
read count
compute count + 1
write count back
So the following interleaving is possible:
initial: count = 0

Thread A                    Thread B

read count -> 0
compute count + 1 -> 1
                            read count -> 0
                            compute count + 1 -> 1
write count -> 1
                            write count -> 1
The final value becomes:
count = 1Both threads complete one +1, but because they read the same old value 0, both compute 1, and one of the updates is overwritten.
The key problem is that two Threads modify count at the same time:
Multiple execution units access and modify the same mutable data concurrently.
Within a single process on a single machine, there are two main models for handling this safely under concurrency:
- Shared Memory: multiple execution units directly share mutable data and coordinate concurrent access through synchronization mechanisms such as locks and atomic operations;
- Message Passing: execution units avoid directly sharing mutable data where possible and exchange data through messages instead.
We will keep using count++ to see how these two models handle the same concurrency problem.
3. Two Main Coordination Models
3.1 Shared Memory
Continue with count.
In Java, the shared state can be protected with synchronization, for example with synchronized:
class Counter {
    private int count = 0;

    public synchronized void increment() {
        count++;
    }
}
Both threads still access the same Counter:
Thread A                    Thread B

counter.increment()         counter.increment()
However, because of synchronized, the two threads cannot enter the critical section in increment() at the same time. In this example, that critical section is count++.
Suppose Thread A acquires the lock first. The execution becomes:
initial: count = 0

Thread A                         Thread B

request to enter increment()
acquire lock
                                 request to enter increment()
                                 cannot acquire the same lock; wait
read count       -> 0
compute count+1  -> 1
write count      -> 1
leave critical section and release lock
                                 acquire lock
                                 read count       -> 1
                                 compute count+1  -> 2
                                 write count      -> 2
                                 leave critical section and release lock

final: count = 2
If Thread B acquires the lock first, the order of A and B is reversed, but the result is still 2.
What matters is not which thread runs first. What matters is that before one thread leaves the critical section, another thread cannot enter the same critical section. The interleaving in which both threads read 0 therefore cannot occur.
Go and Python provide similar mechanisms:
Go      -> Mutex
Python  -> Lock
They share the same idea:
Mutable data is shared directly, but access to it is coordinated through synchronization mechanisms such as locks and atomic operations.
3.2 Message Passing
Continue with count.
For example, in Go:
increments := make(chan int)

go func() { // Counter Owner Goroutine
    count := 0

    for delta := range increments {
        count += delta
    }
}()
The two producer Goroutines do not modify count directly. Instead, they send increments to the same Channel:
go func() { // Goroutine A
    increments <- 1
}()

go func() { // Goroutine B
    increments <- 1
}()
We can abstract this as:
Goroutine A ── +1 ──┐
                     ├──> Channel ──> Counter Owner Goroutine ──> count++
Goroutine B ── +1 ──┘
Both Goroutines only send messages. The actual count is modified by a dedicated Counter Owner Goroutine.
Java and Python provide similar message-passing tools:
- Java
BlockingQueue - Python
queue.Queue/asyncio.Queue
They share the same idea:
Multiple execution units coordinate through messages instead of directly modifying the same state at the same time.
4. Why Does This Code Work Correctly?
So far, we have handled the original count++ problem in two ways.
With Shared Memory, we used synchronization mechanisms:
synchronized / Lock / MutexWith Message Passing, we used:
Channel / QueueBut there is a more fundamental question:
Why does this code work correctly?
To answer it, we need to look at three fundamental properties of concurrent programs:
- Atomicity: when an execution unit performs one or more operations, whether those operations appear to other execution units as one indivisible whole; other execution units cannot observe intermediate states, only the state before or after the operation.
- Visibility: after one execution unit writes data, whether other execution units can observe that write.
- Ordering: when one execution unit performs multiple operations in sequence, whether other execution units observe those operations taking effect in an order consistent with that sequence.
Programmers need to know what guarantees they can rely on across these three dimensions.
That leads us to:
The concurrency semantics defined by the programming language.
5. Languages Need to Define Concurrency Semantics
A programming language needs to define:
When multiple execution units access and modify the same mutable data concurrently, which behaviors are allowed and which rules programmers may rely on.
Java has the:
Java Memory ModelGo has the:
Go Memory ModelPython is somewhat different. In this series, we mainly discuss:
Python / CPython Concurrency SemanticsThese rules need to answer three questions:
| Question | What it means for the count example |
|---|---|
| Atomicity | count++ contains read → increment → write. Without locking, A’s and B’s steps may interleave. With the same lock, the critical section cannot be interleaved by another execution unit using that same lock. |
| Visibility | After A writes count = 1 and releases the lock, B, after acquiring the same lock, must be able to observe that write instead of continuing to use the old value 0. |
| Ordering | A writes count = 1 and then releases the lock; B subsequently acquires the same lock and reads count. The synchronization rules must guarantee that B observes these operations in a way consistent with that order. |
6. Why Do We Still Need to Go Down to the Operating System and Hardware?
Languages define concurrency rules, and those rules are ultimately realized by the operating system and the underlying hardware.
The Operating System manages the execution units on which programs actually run, including thread scheduling, blocking, and wake-up, and provides synchronization primitives such as semaphores, futexes, and condition variables.
Hardware provides lower-level primitives and mechanisms, including atomic instructions, memory-ordering guarantees, CPU caches, and store buffers.
7. A Single Diagram for the Layers Covered in This Series
First, consider the conventional software-to-hardware stack:
Source Code
├──→ Java: Java Application / JDK Source
├──→ Go: Go Application / Standard Library Source
└──→ Python: Python Application / Standard Library Source
        ↓
Compiler / Translator
├──→ Java: javac
├──→ Go: Go Compiler
└──→ Python: CPython Compiler
        ↓
Runtime / Execution Environment
├──→ Java: HotSpot JVM (Interpreter / JIT / Runtime)
├──→ Go: Go Runtime
└──→ Python: CPython Interpreter / Runtime
        ↓
Operating System
└──→ Linux / Windows / macOS
        ↓
Hardware
        │
        ├── ISA ──→ x86-64 / ARM64
        │      ↓
        ├── Microarchitecture ──→ Cache / Store Buffer / Reorder Buffer / Out-of-Order Execution
        │      ↓
        └── Physical Hardware ──→ CPU / DRAM / Interconnect
The Language Memory Model / Concurrency Semantics forms a cross-layer constraint: the Compiler, Runtime, Operating System, and Hardware work together to realize the concurrency guarantees defined by the language.
This series focuses on concurrency. To give the later Mutex, Atomic, Volatile, and related articles a consistent structure, we combine the concurrency rules with the conventional software / hardware stack into one discussion model:
Concurrency Tools
├──→ Java: synchronized / Lock / Atomic / BlockingQueue
├──→ Go: Mutex / Atomic / Channel
└──→ Python: Lock / Queue / asyncio
        ↓
Language Memory Model / Concurrency Semantics
├──→ Java: Java Memory Model
├──→ Go: Go Memory Model
└──→ Python: Python / CPython Concurrency Semantics
        ↓
Runtime / Language Implementation
├──→ Java: HotSpot JVM (Interpreter / JIT / Runtime)
├──→ Go: Go Runtime
└──→ Python: CPython Interpreter / Runtime
        ↓
Operating System
└──→ Threads / Scheduler / Semaphores / Futexes / Condition Variables
        ↓
Hardware
├──→ ISA: x86-64 / ARM64
├──→ Microarchitecture: Cache / Store Buffer / Reorder Buffer / Out-of-Order Execution
└──→ Physical Hardware: CPU / DRAM / Interconnect
8. Next: Start with the Hardware
The next article moves down to the Hardware layer.
It focuses on:
- why CPUs need caches;
- how multiple CPU Cores coordinate cached data;
- why Store Buffers and Out-of-Order Execution affect Memory-access ordering;
- what Atomic Instructions provide.
Discussion
Sign in with GitHub to comment. Discussions are stored as GitHub Issues.View on GitHub