
NOTE
1.12 Cloud Redis
Historical Tencent Cloud Redis notes covering topology, availability-zone deployment, consistency, availability, scalability, cost, parameters, and monitoring.
This is a historical learning note and may contain outdated or incomplete understanding.
1. Tencent Cloud Redis
Based on VIP + LoadBalancer + Proxy + native Redis Cluster.
- VIP + LoadBalancer: the addressing + load-balancing + health-check + nearby-routing functions of the Polaris registry. This VIP binds all data nodes inside the cluster and provides load balancing. All user requests are evenly distributed to the data nodes in the cluster. The VIP also provides health checks. If repeated checks within a period confirm that a node does not respond, the health-check function temporarily removes the problematic node from the VIP binding list until it recovers. This ensures that when a node goes down or an availability zone in a data center becomes unavailable, problematic nodes are automatically removed so clients do not send requests to them. In this way, an availability-zone failure can be switched without the customer business noticing it, improving business stability.
- Proxy: used to implement read/write separation, data statistics, and other functions.
- Native Redis Cluster: version 4.0; supports at most 1 primary + 5 replicas; each node configuration: 1 CPU core, 4 GB memory, disk unknown.
1.1. Deployment
1.1.1. Single Availability Zone in the Same Region
The primary node and replica nodes are in the same availability zone.
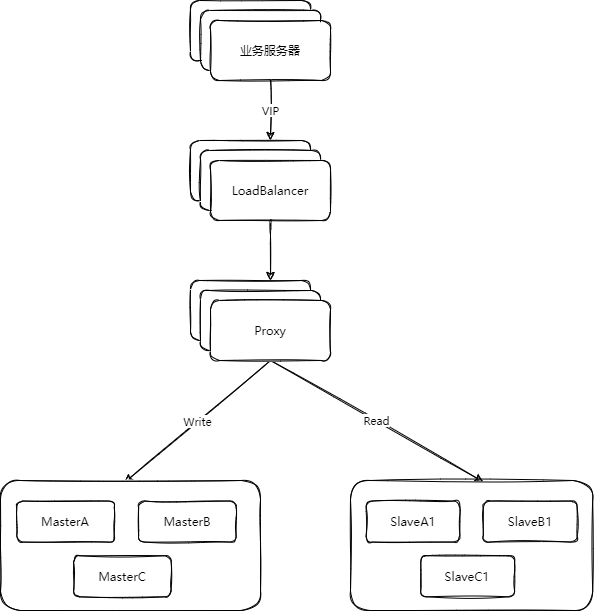
1.1.1.1. Problem
If the single availability zone goes down, clients cannot access it.
1.1.2. Multiple Availability Zones in the Same Region
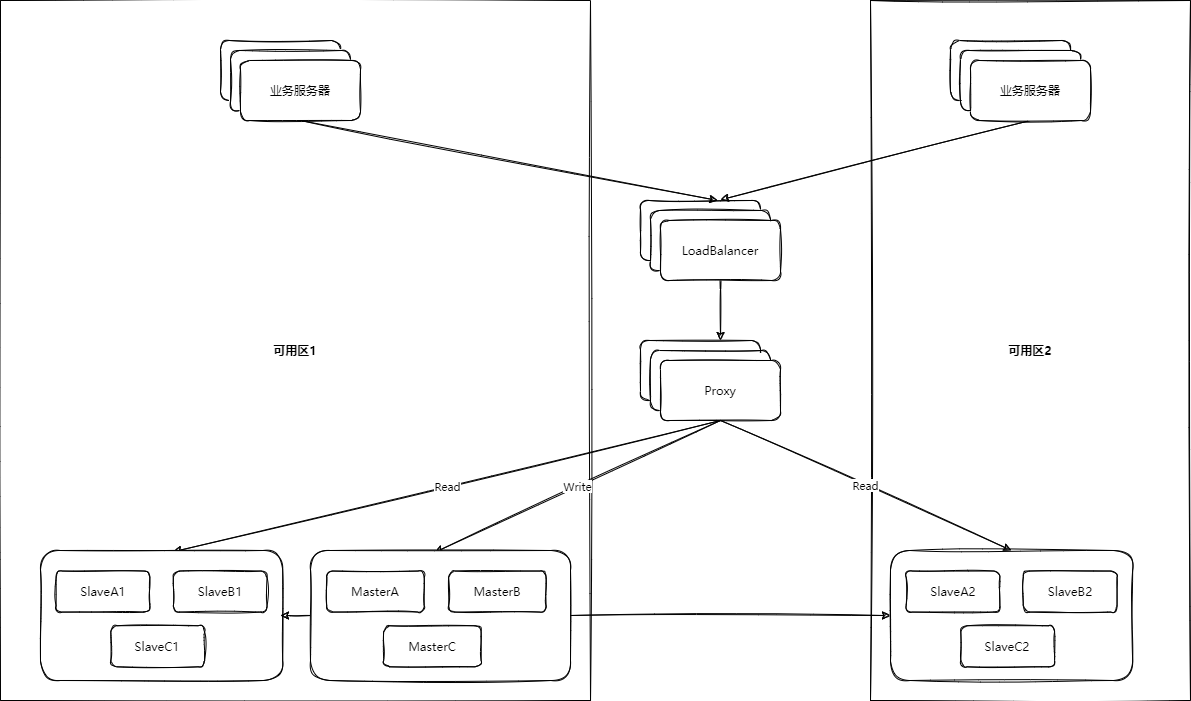
The primary node is in one availability zone, while replica nodes can be in another availability zone in the same region.
Nearby access disabled: 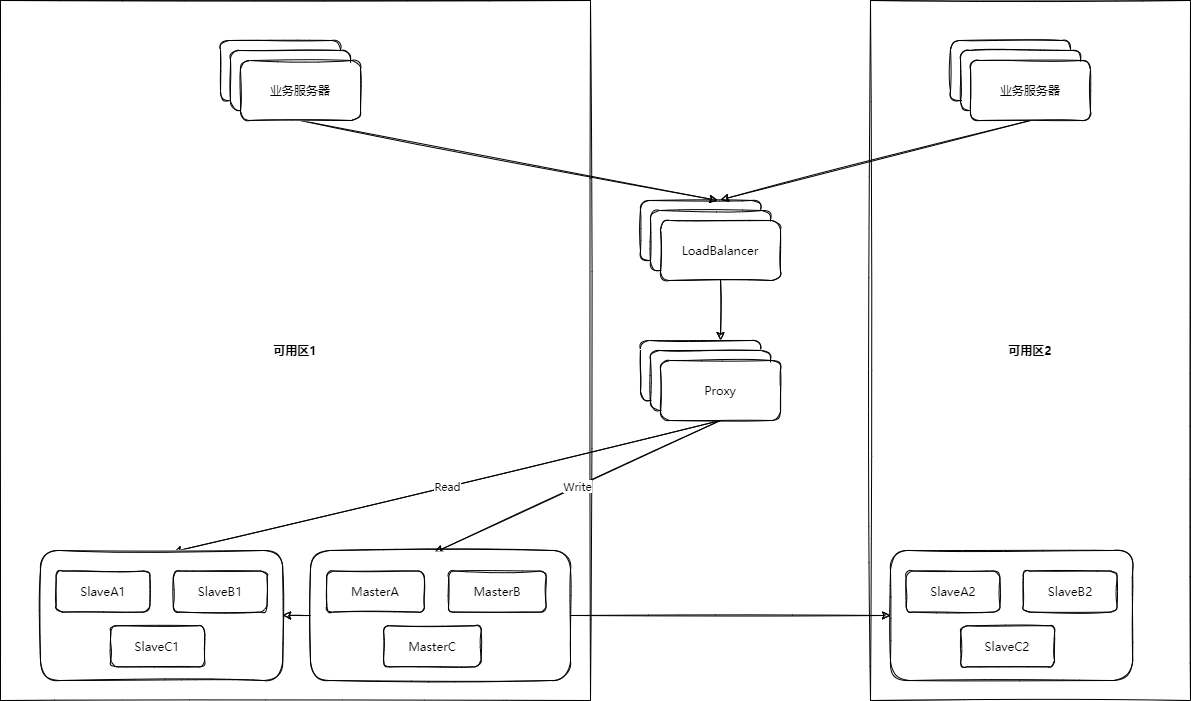 Nearby access enabled:
1.1.2.1. Problems
Suppose there are three master nodes, each master has two slave nodes, all three master nodes are deployed in availability zone A, and for each master one slave is in availability zone A and one slave is in availability zone B.
- A single availability zone becomes unavailable: if availability zone B goes down, availability zone A removes the replica nodes in B from the cluster. After the VIP detects this situation, it routes requests for B to availability zone A and recreates slave nodes in the backup availability zone. If availability zone A goes down, after the VIP detects this situation it promotes the slave nodes in B to master nodes. However, this state is temporary. When conditions are met, the HA system migrates the master nodes back to the primary availability zone within several minutes. The migration process is lossless.
- Network isolation: if availability zones A and B become network-isolated, do they become two clusters? No, because all masters are in the same availability zone. Availability zone A removes the slave nodes in B from the cluster; B triggers subjective-down status, but because of network isolation, the master nodes in A do not respond with objective-down status, so it is equivalent to availability zone B going down.
1.1.3. Multiple Regions and Multiple Availability Zones
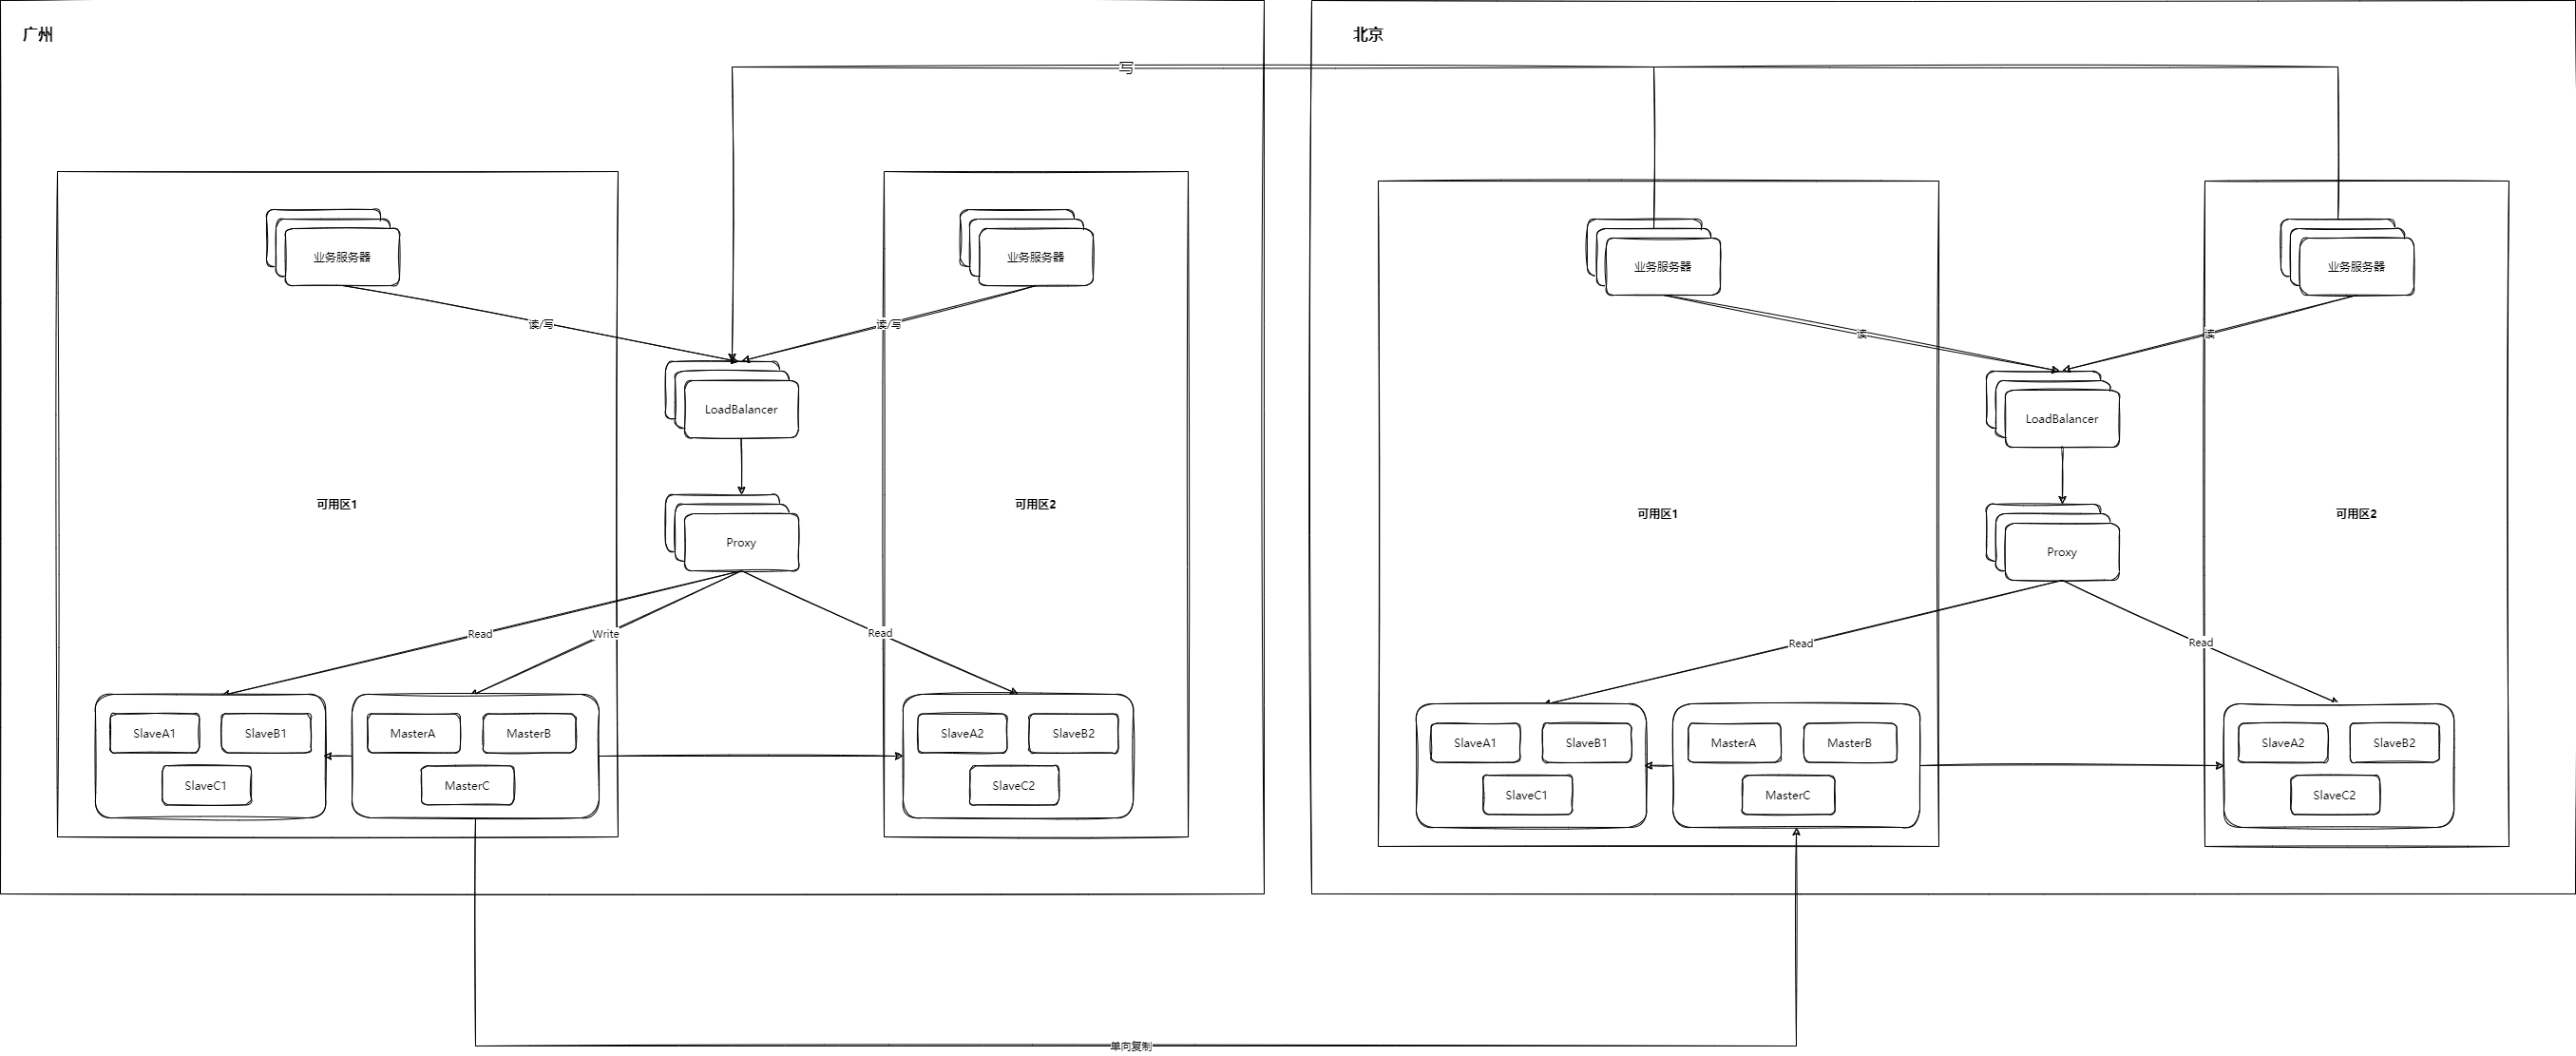
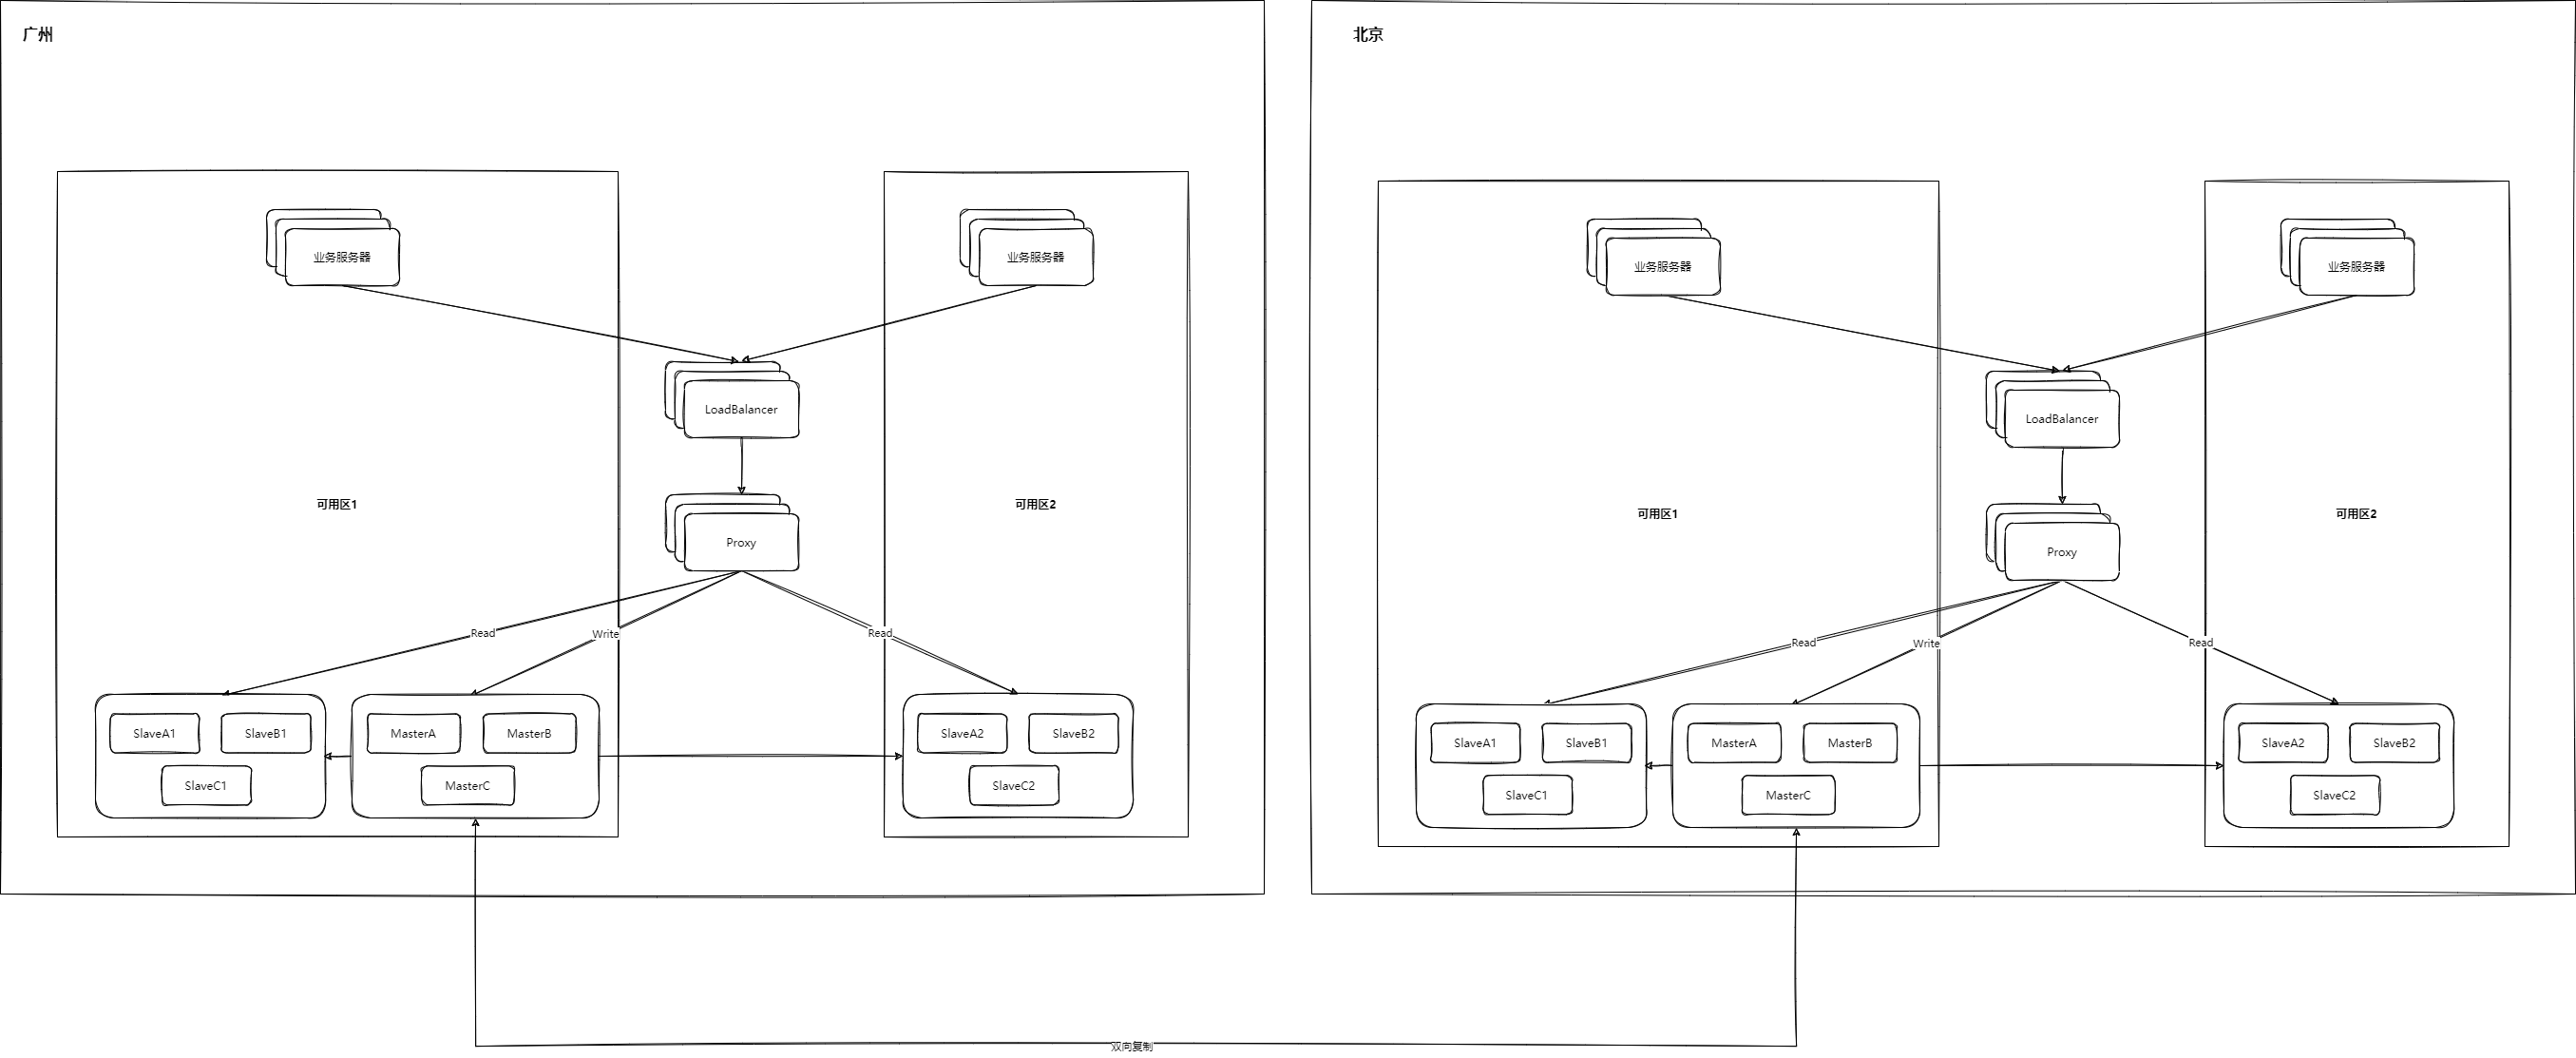
1.1.3.1. Problems
There are two instances: A is the primary instance and B is the secondary instance. Each instance has three master nodes, each master has two slave nodes, all three master nodes are deployed in availability zone A, and for each master one slave is in availability zone A and one slave is in availability zone B.
- A single availability zone becomes unavailable: if one availability zone inside instance A/B goes down, it is the same as multiple availability zones in the same region. If instance B goes down, Polaris automatically routes to instance A. If instance A goes down, a manual switch is required. During the switch, the replication group is briefly inaccessible, usually for 1 minute.
- Network isolation: if one availability zone inside instance A/B becomes network-isolated, it is the same as multiple availability zones in the same region. If instances A and B become isolated from each other, data inconsistency occurs.
1.1.4. Set Deployment
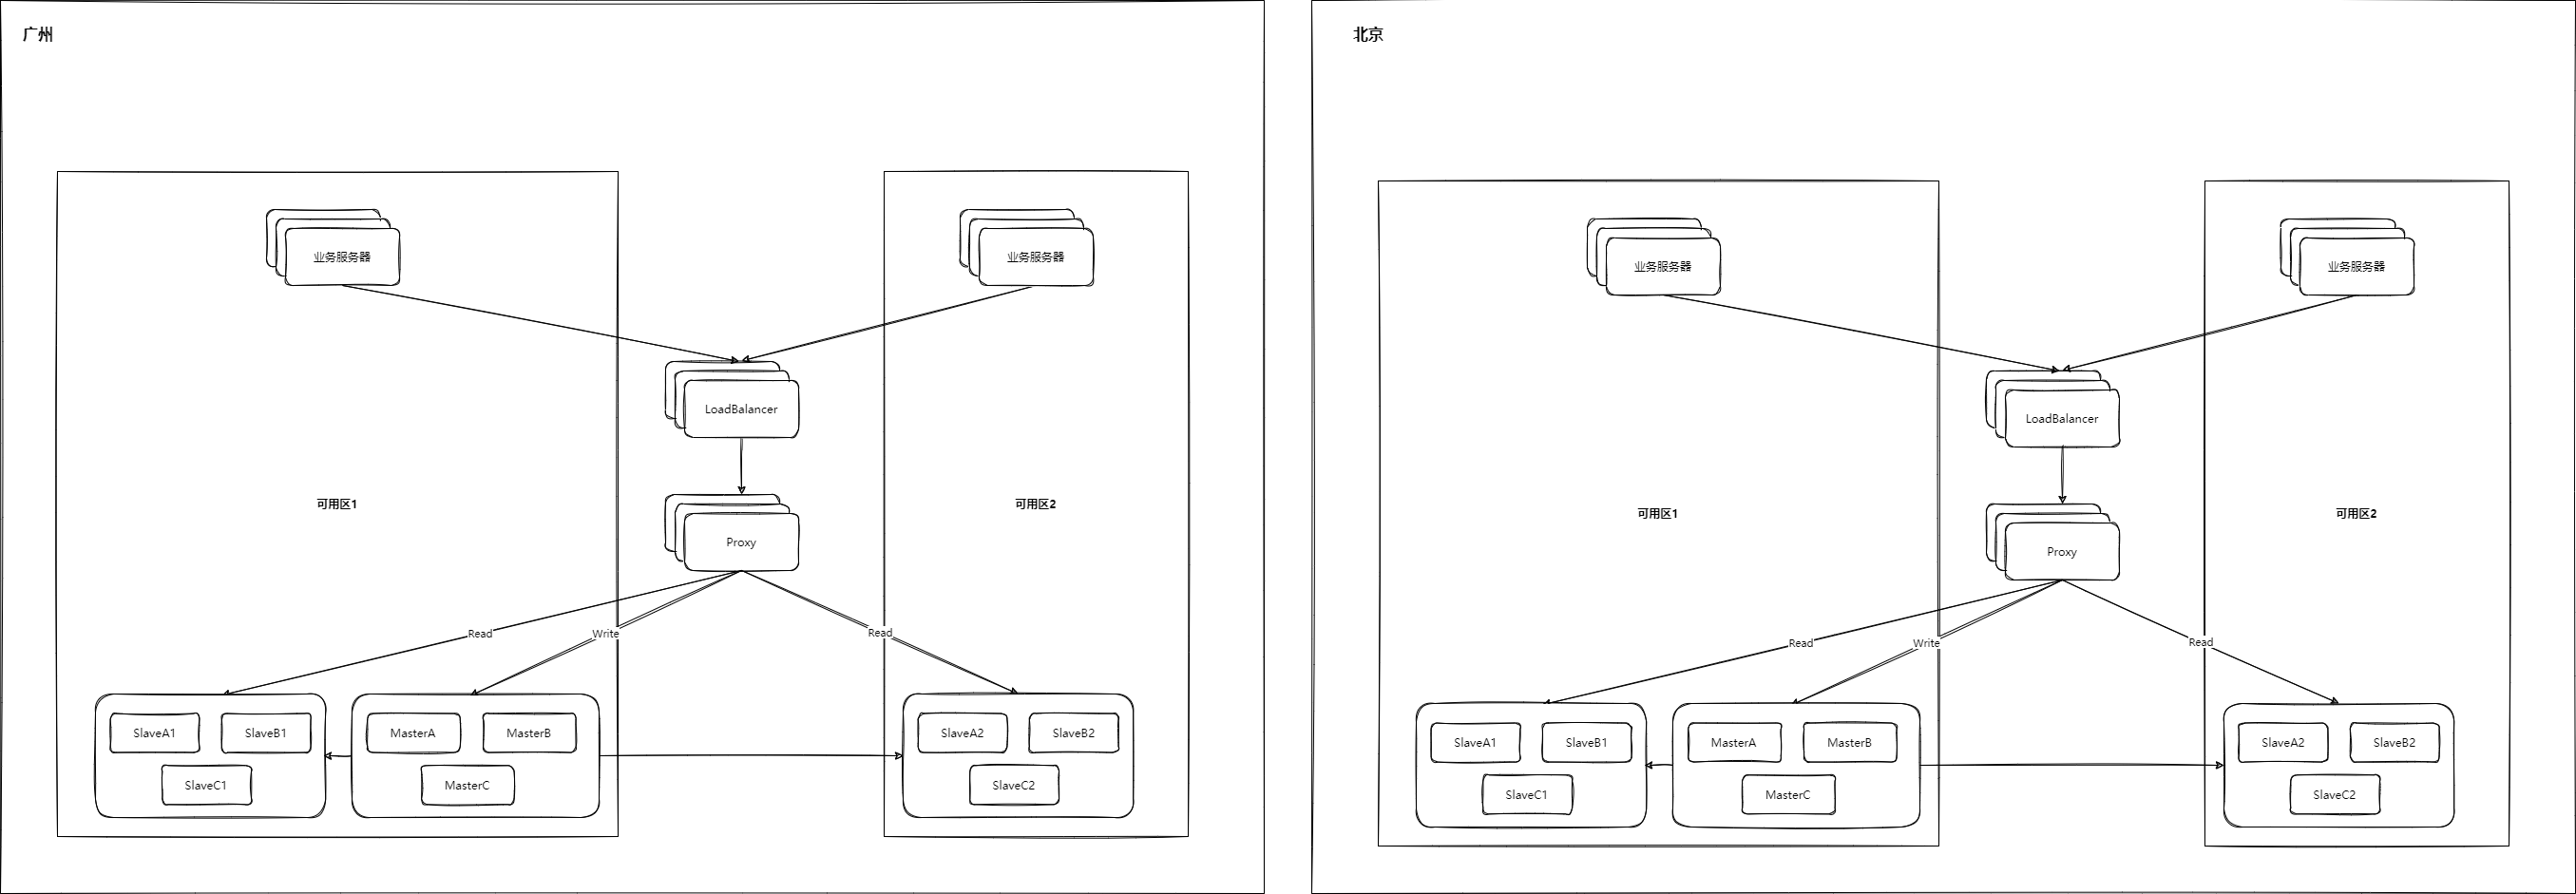
1.1.4.1. Problem
Data across regions cannot be synchronized.
1.1.5. Comparison of the Four
| Single AZ, Same Region | Multiple AZs, Same Region | Multiple Regions, Multiple AZs | Set Deployment | |
|---|---|---|---|---|
| Consistency | High | Medium | Low | Medium |
| Availability | Low | Medium | High | Medium |
| Isolation | Low | Medium | High | High |
1.2. Consistency
1.2.1. Latency
Within the same availability zone it is generally within 1 ms, across availability zones generally within 3 ms, and across regions roughly 30–40 ms. Global replication write-synchronization latency is roughly 20 ms. At this latency, the data-inconsistency rate is roughly 5 in 10,000.
1.3. Availability
1.3.1. SLA
Tencent Cloud provides the following service-availability standards: Availability is not lower than 99.95% for deployment in a single availability zone within the same region. For deployment across multiple availability zones in the same region, when the number of replicas (excluding the primary node) is at least 2, availability is not lower than 99.99%. For a cache service deployed through global replication across multiple regions and multiple availability zones on Tencent Cloud, when a single global-replication instance has at least 2 replicas (excluding the primary node) and the primary-instance role is enabled for all cache instances in the replication group, availability is not lower than 99.999% (in this case, service-unavailable time is calculated according to the actual duration of unavailability even if it lasts less than 1 minute).
1.3.2. Failure Handling
1.3.2.1. Failure Detection
Redis standard architecture and cluster architecture use Redis Cluster’s native cluster-management mechanism, relying on the Gossip protocol among cluster nodes to determine node status. The timeliness of node-failure detection depends on cluster-node-timeout, whose default value is 15 seconds. It is recommended not to change this parameter. For node-failure determination, refer to the native Redis Cluster design.
1.3.2.2. Failure Recovery
Primary-node election: compared with the native Cluster Failover mechanism, Tencent Cloud Redis introduces logic that prioritizes failover to the primary availability zone to protect business-access latency in that zone. The mechanism is: The node with the newest data is preferred as the primary. When data is identical, a replica in the primary availability zone is preferred as the primary.
1.4. Scalability
The ability to scale out quickly is essentially Redis Cluster itself.
1.5. Cost
Redis costs five times as much as a server under the same circumstances. Global replication is only a plugin; its cost is the cost of several Redis instances plus cross-region replication bandwidth.
1.6. Parameters
- Persistence method: the backend of Cloud Database Redis performs full and incremental backups through a backup cluster. Persistence is executed on the standby machine using RDB + AOF and has almost no impact on online business.
- Memory eviction mechanism:
nonevition.
1.7. Monitoring
5-second granularity + minute-level granularity.
2. References
- 云数据库 Redis 内存版(集群架构) - 产品简介 - 文档中心 - 腾讯云
- 云数据库 Redis 地域和可用区-产品简介-文档中心-腾讯云-腾讯云
- 云数据库 Redis 多可用区部署-产品简介-文档中心-腾讯云-腾讯云
- 云数据库 Redis 使用常见问题-常见问题-文档中心-腾讯云-腾讯云
- 云数据库 Redis 设置实例参数-操作指南-文档中心-腾讯云-腾讯云
- 服务等级协议
- 云数据库 Redis 服务等级协议-服务协议-文档中心-腾讯云
- 云数据库 Redis 读写分离-产品简介-文档中心-腾讯云
- 云数据库 Redis 开关读写分离-操作指南-文档中心-腾讯云
- 云数据库 Redis 就近访问-操作指南-文档中心-腾讯云
- 云数据库 Redis 变更实例规格 - 操作指南 - 文档中心 - 腾讯云
- 云数据库 Redis 新建全球复制组 - 操作指南 - 文档中心 - 腾讯云
- 云数据库 Redis 5秒监控更新说明-操作指南-文档中心-腾讯云
Discussion
Sign in with GitHub to comment. Discussions are stored as GitHub Issues.View on GitHub